

In our previous article, Building Durable Job Queues with SQLite, we designed a background processing system that could survive application restarts, recover abandoned jobs, retry failed operations, and prioritize important tasks.
That architecture solved a critical problem: unfinished work should never disappear simply because a worker crashes.
But durability introduces another challenge.
Imagine an application receiving 10,000 background jobs every minute. Its workers can process only 2,000 jobs during that same period.
The remaining 8,000 jobs enter the queue.
After ten minutes, the backlog has grown by 80,000 jobs. After an hour, it has grown by 480,000.
Every job is safely stored in SQLite. Nothing has been lost.
Yet the application is moving toward failure.
The queue consumes more storage, new jobs wait longer, retries compete with fresh work, and important operations become buried beneath an expanding backlog.
A durable queue protects work from being lost. Backpressure protects the application from accepting more work than it can safely handle.
In this article, we’ll design a practical backpressure system using SQLite, combining bounded queues, admission control, workload prioritization, worker capacity, retry management, and overload recovery.
We’ll also explore what happens when an application must choose between accepting new work, delaying it, rejecting it, or reducing its processing requirements.
Why Durable Queues Are Not Enough
A durable job queue separates incoming requests from background execution.
That is useful because the application can acknowledge a request quickly and process it later.
But this separation creates two independent rates:
Arrival rate: How quickly new jobs enter the system.
Processing rate: How quickly workers complete jobs.
When the arrival rate remains higher than the processing rate, the backlog grows.
For example:
Metric                          Value
Incoming jobs per minute        10,000
Completed jobs per minute       2,000
Net backlog growth per minute   8,000
Backlog after 30 minutes        240,000
Backlog after 60 minutes        480,000
These figures assume the queue starts empty, rates remain constant, and no jobs are removed through other means.
Adding more durable storage does not solve the underlying imbalance.
Eventually, the application must control how much work it accepts.
That is the purpose of backpressure.
What Backpressure Actually Means
Backpressure is a mechanism that prevents a system from becoming overwhelmed when work arrives faster than it can be processed.
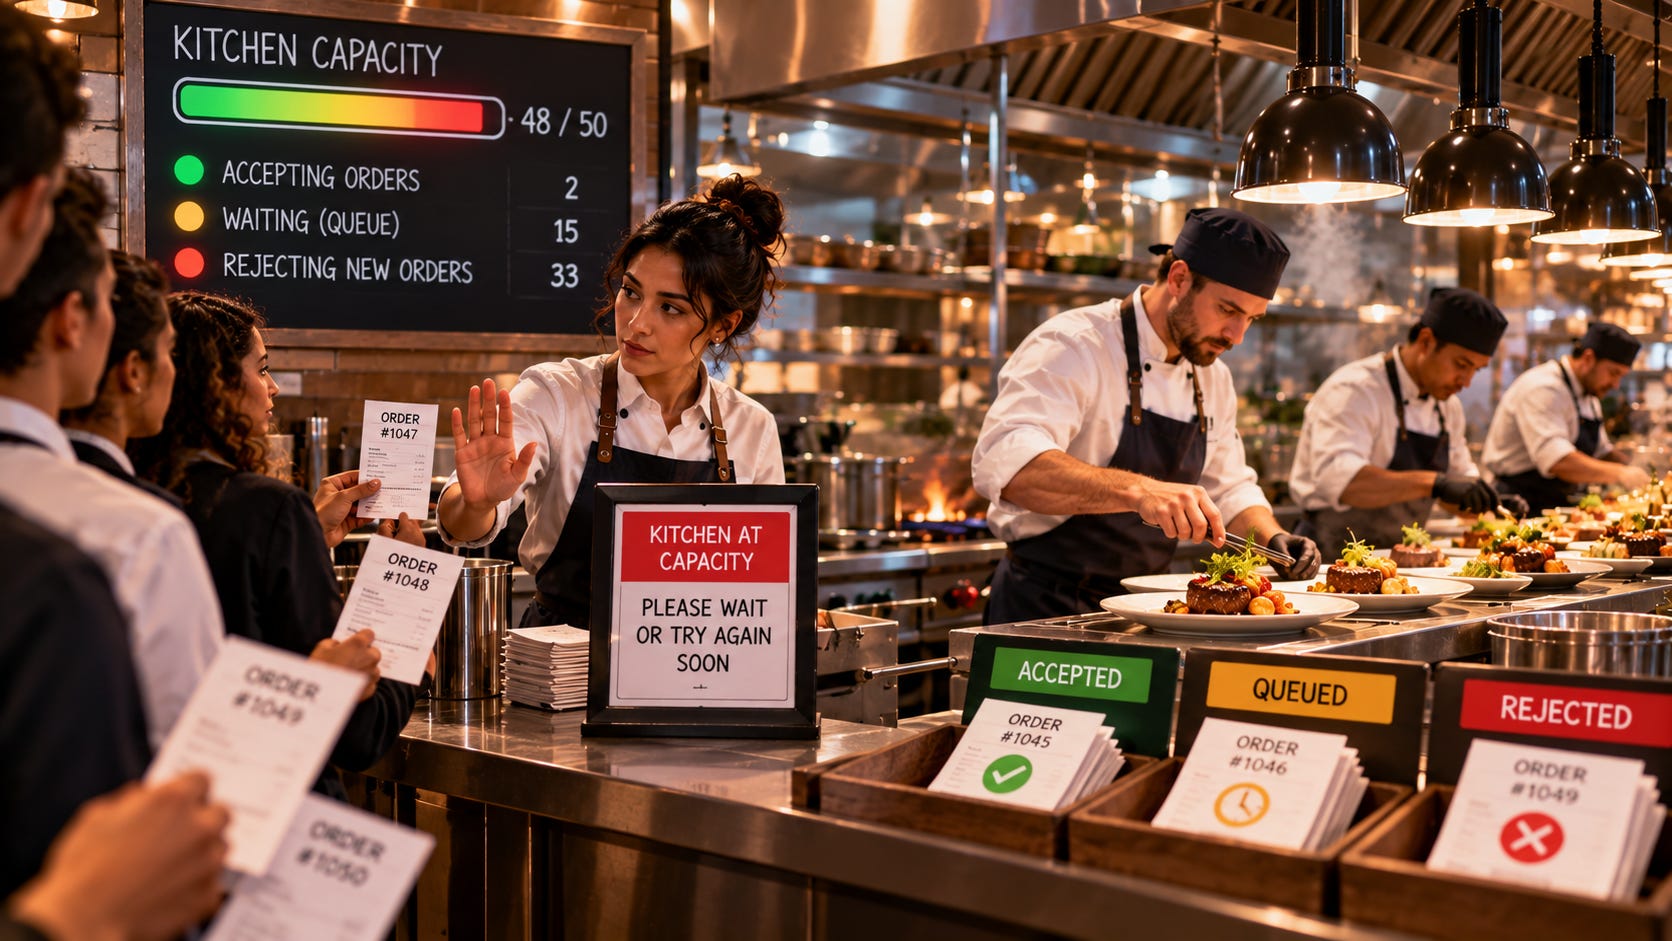
Consider a busy restaurant.
The kitchen can prepare 40 meals per hour, but customers begin placing 100 orders per hour.
If the restaurant continues accepting every order without restriction, the kitchen becomes overloaded.
Customers wait longer, ingredients run out, and service quality declines.
A better approach is to control incoming orders based on kitchen capacity.
The restaurant might limit reservations, delay new orders, prioritize urgent dietary requirements, or temporarily stop accepting certain requests.
Software systems face the same problem.
Incoming Requests
        |
        v
Admission Control
        |
        +---- Capacity available ----> SQLite Job Queue
        |                                  |
        |                                  v
        |                            Background Workers
        |                                  |
        |                                  v
        |                              Completed
        |
        +---- Capacity exceeded
                    |
                    +---- Reject
                    +---- Delay
                    +---- Reduce workload
The key idea is that the application must make a capacity decision before adding more work to an already overloaded system.
SQLite can help enforce that decision through durable counters, transactional admission rules, and observable queue state.
Understanding the Three Types of Overload
Before implementing backpressure, distinguish three problems that may look similar.
1. Temporary Traffic Spikes
An application normally receives 500 jobs per minute but briefly receives 3,000.
Workers can process 1,000 per minute.
A temporary backlog forms, but workers can eventually clear it after traffic returns to normal.
A bounded queue can absorb this spike without rejecting every excess request.
2. Sustained Overload
The application consistently receives 5,000 jobs per minute while workers process only 1,000.
The backlog grows indefinitely unless incoming work is reduced or processing capacity increases.
This requires admission control, workload reduction, or scaling.
3. Processing Failure
Workers normally process 1,000 jobs per minute but suddenly complete almost nothing because an external service is unavailable.
Even ordinary traffic becomes excessive.
In this case, accepting more work may worsen the situation.
The correct response depends on the cause of overload. A larger queue helps with short spikes, but not sustained imbalance or a stalled downstream service.
Start with a Bounded Queue
An unbounded queue accepts jobs until storage or another system resource runs out.
That makes it dangerous for applications operating with limited disk space.
A bounded queue defines how much outstanding work the system can retain.
For example:
Maximum outstanding jobs: 50,000

Current outstanding jobs: 42,000
Available capacity:        8,000
When the queue reaches its limit, new work must follow an explicit overload policy.
However, a simple COUNT(*) check is not enough.
Consider two concurrent requests:
Request A checks queue size: 49,999
Request B checks queue size: 49,999

Request A inserts a job
Request B inserts a job
Both requests believe capacity is available.
The queue exceeds its configured limit.
To enforce a hard limit, capacity checks and reservations must happen atomically.
Designing a SQLite Admission-Control Table
Instead of repeatedly counting every job, maintain a small table containing the configured capacity and current usage.
Example:
CREATE TABLE QueueCapacity (
    QueueName TEXT PRIMARY KEY,

    MaxOutstanding INTEGER NOT NULL
        CHECK (MaxOutstanding > 0),

    OutstandingCount INTEGER NOT NULL DEFAULT 0
        CHECK (OutstandingCount >= 0),

    CHECK (OutstandingCount <= MaxOutstanding)
);
Initialize a queue:
INSERT INTO QueueCapacity (
    QueueName,
    MaxOutstanding,
    OutstandingCount
)
VALUES (
    'background',
    50000,
    0
);
Here, OutstandingCount represents jobs that have been accepted but have not yet reached a terminal state.
It includes pending and running jobs.
Completed and permanently failed jobs no longer consume execution capacity, although their retained records still consume disk space.
This distinction matters because a job-count limit is not the same as a storage-space limit.
We’ll address storage separately.
Enforcing Admission Control Atomically
When a new job arrives, the application first reserves one unit of capacity.
Example:
BEGIN IMMEDIATE;

UPDATE QueueCapacity
SET OutstandingCount = OutstandingCount + 1
WHERE QueueName = 'background'
  AND OutstandingCount < MaxOutstanding;
The application must inspect the number of updated rows.
If exactly one row was updated, capacity was reserved.
It can then insert the job:
INSERT INTO JobQueue (
    JobType,
    Payload,
    Status,
    Priority,
    CreatedAt,
    ScheduledAt
)
VALUES (
    :job_type,
    :payload,
    'pending',
    :priority,
    :now,
    :now
);

COMMIT;
This example reuses the JobQueue table from the previous article.
If the capacity update affects zero rows, the application must roll back and reject or defer the request according to its overload policy.
If the insert fails, the transaction must also roll back, restoring the capacity counter.
Because the reservation and insertion occur inside one SQLite write transaction, concurrent writers cannot independently reserve the same final slot.
The application should return success only after the transaction commits.
For production use, every path that inserts a job must follow the same admission protocol. Alternatively, database triggers can enforce counter updates centrally, provided they are designed to avoid double counting.
Releasing Capacity When Jobs Finish
Reserving capacity is only half the design.
The application must release that capacity when a job reaches a terminal state.
For example, when a worker successfully completes a job:
BEGIN IMMEDIATE;

UPDATE JobQueue
SET
    Status = 'completed',
    CompletedAt = :now,
    LeaseOwner = NULL,
    LeaseToken = NULL,
    LeaseExpiresAt = NULL
WHERE JobID = :job_id
  AND Status = 'running'
  AND LeaseToken = :lease_token
  AND LeaseExpiresAt > :now;
If exactly one row was updated, the application releases the reserved slot:
UPDATE QueueCapacity
SET OutstandingCount = OutstandingCount - 1
WHERE QueueName = 'background'
  AND OutstandingCount > 0;

COMMIT;
Both updates must succeed in the same transaction.
If the job completion update affects zero rows, the worker must roll back without decrementing the counter.
The same principle applies when a job becomes permanently failed or is explicitly cancelled.
A retryable failure does not release capacity because the job is still outstanding.
This creates an important invariant:
Every accepted job reserves capacity once, and every job releases it exactly once when it leaves the active workload.
For this example, the counter assumes a single named queue and a job table dedicated to it. A multi-queue implementation should store each job’s queue identity and update the matching counter.
What Happens When the Queue Is Full?
A full queue is not necessarily a software error.
It may mean the system is protecting itself as designed.
The application needs a clear policy for incoming work.
Four common approaches are available.
Reject New Work
For an HTTP API, return an appropriate overload response such as 503 Service Unavailable, optionally with a Retry-After header when a useful retry interval can be estimated.
A 429 Too Many Requests response is also appropriate when admission is being restricted by a client-specific rate or quota policy.
The application must not report that a job was accepted if it was never durably stored.
Delay the Request
The application may wait briefly for capacity to become available.
This works when overload is temporary and the caller can tolerate additional latency.
However, waiting requests consume server resources.
Unlimited waiting simply moves the queue from SQLite into application memory.
Always enforce a timeout and a maximum number of waiting requests.
Reduce the Workload
Some tasks can be combined, summarized, or replaced by newer requests.
For example, a dashboard may not need 100 separate refresh jobs if one refresh can produce the latest state.
This is workload coalescing.
It reduces processing demand rather than merely delaying it.
Redirect or Scale
Some architectures can move work to another service or increase worker capacity.
But adding workers only helps when the actual bottleneck can support more concurrency.
If all workers depend on one slow external API, adding more workers may make the overload worse.
Protecting Important Work with Priority-Aware Capacity
Our previous article introduced job priorities.
Higher-priority jobs are selected first.
But prioritization alone does not protect admission.
Imagine a queue containing 50,000 low-priority maintenance jobs.
A critical security notification arrives.
The queue is already full.
Even though the new job has higher execution priority, it cannot enter the queue.
This is why admission control and scheduling priority must be designed together.
One practical solution is reserved capacity.
For example:
Workload                 Maximum outstanding jobs
Critical operations      5,000
User-facing tasks        15,000
Routine background work  30,000
Total                    50,000
Each workload can have its own capacity counter and admission policy.
The worker scheduler can then allocate execution capacity across these groups.
This prevents routine jobs from consuming every available slot.
A more flexible implementation could allow critical work to borrow unused capacity from other groups, but that requires additional transactional accounting.
Start with explicit limits before introducing complex capacity-sharing rules.
Preventing Retry Storms
Retries are essential for reliable background processing, but they can also create additional load.
Suppose 2,000 jobs fail because an external API becomes unavailable.
Each job is scheduled to retry after 30 seconds.
When those 30 seconds pass, all 2,000 jobs become eligible simultaneously.
The external API receives another large burst of requests, potentially causing another failure.
This is a retry storm.
Use Exponential Backoff and Jitter
Instead of retrying every job at the same interval, spread retries across time.
For example:
Attempt     Base delay      Randomized retry window
1           5 seconds       0–5 seconds
2           10 seconds      0–10 seconds
3           20 seconds      0–20 seconds
4           40 seconds	    0–40 seconds
5           80 seconds      0–80 seconds
These windows illustrate full jitter, where the application selects a random delay up to the capped exponential backoff value.
The worker stores the resulting timestamp in ScheduledAt.
However, backoff alone is insufficient.
A system with limited capacity should also control how many retry jobs execute concurrently.
For example:
Maximum active API calls: 20

Current active API calls: 20

Additional retry jobs: Wait
The worker scheduler can enforce a concurrency limit per external service.
This prevents the retry mechanism from overwhelming the very dependency it is trying to reach.
Controlling Worker Concurrency
Increasing the number of workers is a common response to a growing queue.
But more workers do not always mean more throughput.
Consider an application where each job performs three operations:
Read a record from SQLite.
Call an external service.
Update the job’s completion state.
If the external service supports only 20 concurrent requests, launching 100 workers may increase timeouts rather than improve performance.
A better design uses bounded worker concurrency.
SQLite Job Queue
       |
       v
Worker Scheduler
       |
       +---- Worker 1
       +---- Worker 2
       +---- Worker 3
       ...
       +---- Worker 20

Additional jobs remain pending
For a single application process, a bounded worker pool or semaphore can enforce this limit.
For multiple processes, use coordinated capacity reservations or another shared concurrency-control mechanism.
SQLite leases determine which worker owns a job. They do not, by themselves, impose a global limit on the number of running jobs.
Also, workers should not hold SQLite write transactions open while performing slow operations. SQLite’s WAL mode allows readers and a writer to make progress concurrently, but it does not permit multiple simultaneous writers to the same database.
Applying Backpressure Before Expensive Work Begins
Admission control is most effective when it happens early.
Consider an API that accepts uploaded documents for processing.
A poor design might:
Receive request
      ↓
Upload large file
      ↓
Parse document
      ↓
Prepare processing data
      ↓
Check queue capacity
      ↓
Reject request
By the time the request is rejected, the application has already consumed network bandwidth, memory, CPU, and temporary storage.
A better design checks capacity before expensive processing begins.
Receive request
      ↓
Check admission policy
      ↓
Capacity available?
      |
      +---- No ----> Reject or defer
      |
      +---- Yes
             ↓
       Reserve capacity
             ↓
       Accept work
             ↓
       Persist job
For large uploads, the application may reserve capacity before accepting the file, then release the reservation if the upload fails.
Such reservations also need expiration and recovery rules. Otherwise, abandoned uploads could consume capacity indefinitely.
Backpressure should protect the resources used to accept work, not only the workers that eventually execute it.
Using Queue Age as an Overload Signal
A queue containing 10,000 jobs may be healthy if workers process 50,000 jobs per minute.
The same queue may be severely overloaded if workers process only 100 jobs per minute.
Queue length alone does not tell the full story.
Queue waiting time is often more useful.
Example:
SELECT
    COUNT(*) AS ReadyJobs,
    MIN(ScheduledAt) AS OldestScheduledAt
FROM JobQueue
WHERE Status = 'pending'
  AND ScheduledAt <= :now;
The application can calculate how long the oldest eligible job has been waiting since its scheduled execution time.
Suppose:
Pending jobs: 8,000
Oldest eligible job delay: 45 minutes
That indicates a substantial backlog.
But consider:
Pending jobs: 8,000
Oldest eligible job delay: 2 seconds
The second system may be processing a large burst successfully.
This is why useful backpressure decisions consider queue depth, waiting time, processing throughput, and downstream health together.
Designing Adaptive Admission Control
Fixed queue limits are useful, but some applications benefit from adjusting their behavior as load changes.
For example, define three operating conditions.
Condition        Example signal                      Admission behavior
Normal           Low backlog and healthy workers     Accept eligible work
Elevated         Queue age increasing                Restrict routine work
Critical         Capacity nearly exhausted           Reject most nonessential work
These are application-defined states, not built-in SQLite features.
A simple policy might be:
Queue utilization below 70%
Accept normally

Queue utilization 70%–90%
Restrict low-priority work

Queue utilization above 90%
Accept critical work only
The thresholds are illustrative and should be established through load testing.
Avoid Rapidly Switching Between States
If admission rules change every time utilization crosses a single threshold, the system may repeatedly open and close admission.
For example:
Utilization reaches 90% → Restrict
Utilization falls to 89% → Resume
Utilization reaches 90% → Restrict
This is called flapping.
Use hysteresis instead.
The system might enter restricted mode at 90% utilization but remain restricted until utilization falls below 75%.
That creates a stable recovery window.
Protecting SQLite from Disk-Space Exhaustion
Limiting job count is necessary, but not sufficient.
We explored a related challenge in SQLite as a Durable Store-and-Forward Buffer, where prolonged network outages can cause locally stored data to accumulate. The same capacity-planning principles apply to backpressure, especially when applications must preserve critical work without exhausting available storage.
One job might contain a 200-byte payload.
Another might contain several megabytes.
A queue with 10,000 small jobs may consume less space than one containing 100 large jobs.
SQLite also requires space for indexes, transaction journals or WAL files, and other database operations.
A practical storage policy should monitor:
Database file size
WAL file size
Available filesystem space
Average and maximum job payload size
Rate of new data growth
Retention and cleanup progress
For workloads with large payloads, consider storing the payload in a separate durable file or object store and keeping a reference in SQLite.
However, the application must coordinate the lifecycle of the payload and its queue record. A reference to a missing file is not a durable job.
SQLite’s WAL file also deserves attention. Long-running readers can interfere with checkpoint progress, allowing the WAL to grow. Checkpoint behavior should therefore be monitored rather than assuming the WAL will always remain small.
Recovering When Capacity Counters Become Incorrect
Our admission-control design uses a counter rather than counting the queue for every incoming request.
That improves admission efficiency, but introduces a requirement: the counter must remain consistent with actual job states.
Suppose a software bug updates a job directly without releasing its capacity reservation.
The queue may eventually reject new work even though slots should be available.
To detect this, periodically compare the stored counter with the actual outstanding jobs.
Example:
SELECT COUNT(*) AS ActualOutstanding
FROM JobQueue
WHERE Status IN ('pending', 'running');
Compare the result with:
SELECT OutstandingCount
FROM QueueCapacity
WHERE QueueName = 'background';
For a single-queue system, these values should match.
If they differ, investigate the cause before repairing the counter.
A controlled reconciliation process can recompute the value inside a write transaction, with job writers using the same database and transaction protocol.
Do not allow a background reconciliation process to overwrite counters based on an old snapshot while jobs are being admitted or completed.
The purpose of reconciliation is to restore a broken invariant, not replace proper transactional accounting.
Example: Protecting an IoT Monitoring Platform
Consider an industrial monitoring platform receiving sensor readings from 500 remote devices.
Each device sends readings every few seconds.
SQLite stores incoming data locally and schedules background jobs for aggregation, anomaly analysis, alert generation, and synchronization.
Under normal conditions, workers process incoming jobs faster than they arrive.
Then a network outage occurs.
Synchronization jobs begin failing.
Retries accumulate.
Meanwhile, devices continue producing new telemetry.
Without backpressure, the queue grows until the device runs low on storage.
Step 1: Separate Workloads
The application classifies work into distinct categories.
Workload                   Importance            Overload policy
Critical alerts	           Highest               Reserve capacity
Raw telemetry persistence  High	                 Protect according to data-loss requirements
Aggregation                Medium                Batch or defer
Cloud synchronization      Medium                Retry with backoff
Dashboard refresh          Low                   Coalesce repeated requests
Step 2: Bound Outstanding Work
Each job category receives a capacity policy.
Routine refresh jobs cannot consume capacity reserved for critical alerts.
Step 3: Reduce Redundant Processing
If 100 dashboard refresh requests arrive while one refresh is already pending, the application may combine them into one job.
That is appropriate because the dashboard needs the latest state, not 100 identical refresh operations.
Raw sensor readings require a different policy. If every measurement must be retained, silently dropping or combining readings would violate the system’s requirements.
Step 4: Slow Synchronization Retries
During the outage, synchronization jobs use exponential backoff and jitter.
The system also limits concurrent network requests.
Step 5: Preserve Local Storage
If storage utilization approaches a critical threshold, the application stops accepting nonessential work.
Where the business permits it, older telemetry may be aggregated into retained summaries using an explicit retention policy.
Step 6: Recover Gradually
When connectivity returns, the application does not immediately launch every delayed synchronization job.
It increases processing gradually, observing throughput, error rates, and queue age.
This avoids creating a new overload as soon as the original failure disappears.
The result is a system that continues protecting its most important operations even when resources become constrained.
Monitoring Backpressure in Production
Backpressure should be visible to operators.
Useful metrics include:
Queue utilization percentage
Job admission rate
Job rejection rate
Processing throughput
Oldest eligible job age
Retry backlog
Worker utilization
Active external requests
Available disk space
Time spent in restricted admission mode
A rising rejection rate is not always evidence that backpressure is failing.
It may show that admission control is successfully protecting the application.
The more important question is whether the system is preserving critical operations and recovering when demand returns to manageable levels.
Alerts should distinguish between temporary traffic spikes and sustained overload.
For example, a short queue spike may be harmless, while steadily increasing queue age over 30 minutes may require intervention.
Common Backpressure Mistakes
Several designs create the appearance of overload protection without actually solving the problem.
Increasing queue size indefinitely: This delays failure but does not resolve sustained excess demand.
Adding unlimited workers: This can overwhelm databases, APIs, and other shared resources.
Retrying immediately: This can amplify an outage into a retry storm.
Using priorities without admission limits: Important jobs may still be rejected because routine work occupies every slot.
Counting only pending jobs: Running jobs also represent outstanding work and consume resources.
Rejecting after expensive processing: This wastes resources before admission control can protect them.
Dropping work silently: This violates durability expectations when callers believe their requests were accepted.
Ignoring disk usage: A bounded job count does not guarantee bounded storage consumption.
Treating backpressure as a SQLite setting: Backpressure is an application architecture built around capacity policies, not a single database configuration option.
Best Practices for SQLite Backpressure
A reliable backpressure implementation should follow these principles:
Define how much outstanding work the application can safely retain.
Reserve queue capacity transactionally before accepting jobs.
Release capacity only when jobs reach terminal states.
Protect critical workloads with reserved capacity.
Limit worker concurrency according to real processing bottlenecks.
Apply backoff and jitter to retryable failures.
Coalesce redundant work when business requirements permit it.
Measure queue waiting time alongside queue length.
Use hysteresis to avoid unstable admission-policy changes.
Monitor disk space independently of job count.
Reconcile capacity counters and investigate inconsistencies.
Test sustained overload, worker failures, and recovery before deployment.
Closing Thoughts
A durable job queue ensures that background work survives crashes and restarts.
Backpressure ensures that the same queue does not overwhelm the application it was designed to protect.
SQLite provides the transactional foundation for implementing bounded queues, capacity reservations, workload classification, and durable admission decisions.
But effective backpressure requires more than SQL.
It requires understanding processing capacity, deciding which work matters most, controlling retries, and establishing clear policies for overload.
The most important principle is simple:
A reliable application must know when to stop accepting work, not just how to process it.
And that leads us to another important reliability challenge.
What happens when a business operation updates SQLite successfully but fails before publishing the corresponding event to another service?
Or when the event is published, but the application crashes before recording that publication?
Backpressure controls how much work enters the system. Our next topic addresses how database changes and outgoing messages can remain reliably connected.
Coming Next: Implementing the Transactional Outbox Pattern with SQLite
Reliably publishing events without losing messages between database commits and external delivery.
Subscribe Now
Build SQLite Applications That Stay Reliable Under Pressure
A reliable application doesn’t just handle incoming work. It knows when to slow down, protect critical operations, and prevent overload before it becomes a failure.
Subscribe to SQLite Forum for practical tutorials on backpressure, durable job queues, workload management, performance optimization, and production-ready SQLite architecture.
Subscribe Now and keep building SQLite applications that remain stable, even when demand exceeds capacity.