

In our previous article, Downsampling Time-Series Data with SQLite, we solved an important problem: what happens when sensor data keeps arriving faster than we want our database to grow?
We transformed raw readings into minute, hourly, and daily rollups, giving us an efficient historical view without keeping every measurement forever.
But once we have all that sensor data, another question becomes much more interesting:
How do we know when something unusual is happening?
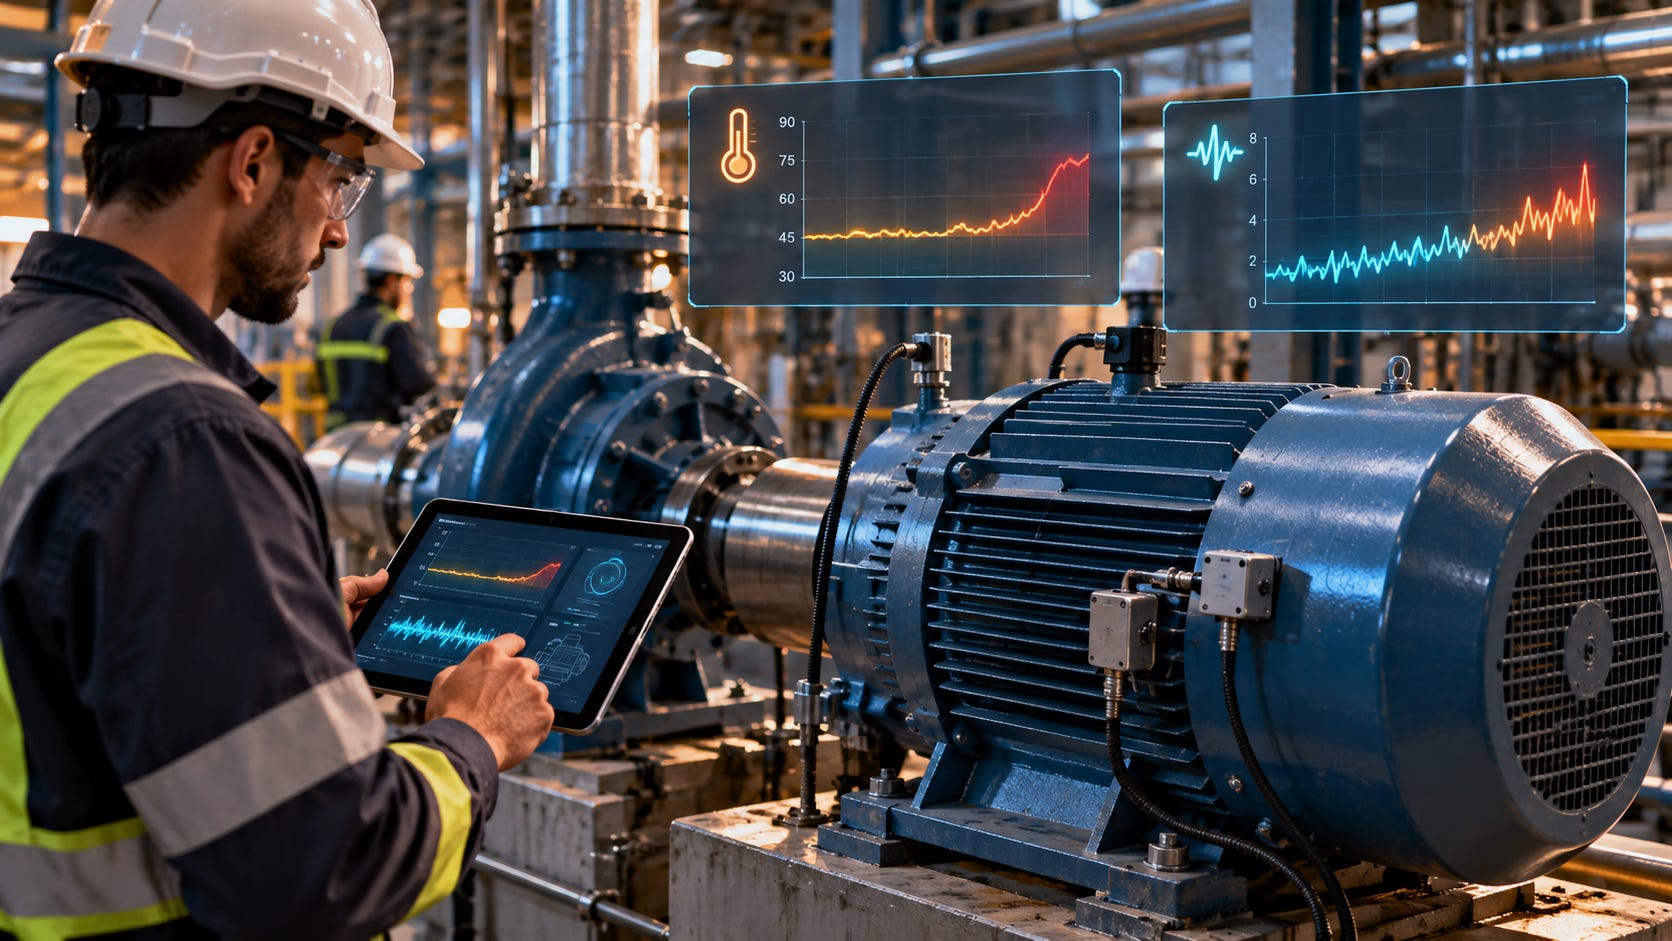
Imagine a motor that normally operates between 55°C and 65°C. One afternoon, its temperature reaches 72°C.
That looks suspicious.
But what if the motor routinely reaches 75°C during heavy production? Then 72°C might be perfectly normal.
Or imagine a vibration sensor that usually reports around 2.0 mm/s. It slowly rises to 2.8, then 3.1, then 3.5.
No single measurement looks catastrophic. The pattern is what matters.
This is anomaly detection.
And for many local monitoring systems, we can perform surprisingly useful anomaly detection directly inside SQLite.
We don’t need to start with machine learning. Rolling averages, standard deviations, historical baselines, window functions, and carefully designed SQL can detect many important changes while keeping the entire analysis close to the data.
What Is an Anomaly?
An anomaly is a measurement or pattern that differs significantly from what we expect.
The important word is expect.
Consider these temperature readings:
21.1
21.3
21.2
21.4
34.8
21.3
The 34.8 immediately stands out.
That’s an obvious point anomaly.
But real sensor systems produce more complicated situations.
Suppose we see:
21.1
21.3
21.6
22.0
22.5
23.1
23.8
24.6
There isn’t one dramatic spike.
Instead, the system is drifting.
Or consider:
08:00    62°C
14:00    72°C
If 72°C is unusual at 08:00 but normal at 14:00, then time and operating context matter.
Anomaly detection is therefore not simply:
value > thresholdIt is often:
value differs significantly
from what is normal
for this sensor
under these conditions
at this time
That’s a much more useful problem to solve.
Start with Simple Thresholds
Before reaching for statistics, don’t underestimate fixed thresholds.
Suppose a refrigeration system must remain between 2°C and 8°C.
We can detect violations with:
SELECT
    DeviceID,
    MetricID,
    Value,
    RecordedAt
FROM Telemetry
WHERE MetricID = ?
  AND (Value < 2.0 OR Value > 8.0);
This is fast, easy to understand, and often exactly what a safety requirement needs.
If 8°C is an absolute operating limit, we don’t need a statistical model to tell us that 11°C is a problem.
But fixed thresholds have an obvious weakness.
They detect values outside predefined limits. They don’t necessarily detect values that are unusual for the current behavior of the system.
That’s where baselines become useful.
A Baseline Defines Normal
Suppose a pump’s vibration normally sits around:
2.0 mm/sA reading of:
3.2 mm/smight still be below the manufacturer’s danger threshold.
But if the pump has spent the last month between 1.8 and 2.2, then 3.2 deserves attention.
We can create a simple baseline from historical data:
SELECT
    AVG(Value) AS MeanValue,
    MIN(Value) AS MinimumValue,
    MAX(Value) AS MaximumValue
FROM Telemetry
WHERE DeviceID = ?
  AND MetricID = ?
  AND RecordedAt >= ?
  AND RecordedAt < ?;
Suppose this produces:
Average: 2.04
Minimum: 1.76
Maximum: 2.31
Now a reading of 3.2 looks much more meaningful.
Instead of asking:
Is this value beyond a universal threshold?
we can ask:
Is this value unusual compared with this device’s normal behavior?
That distinction is central to useful anomaly detection.
Why One Global Baseline Can Be Misleading
Imagine a solar installation.
Power output at noon might normally be:
4,500 WAt midnight:
0 WA global average across the entire day could produce something like:
1,900 WBut that value doesn’t represent normal behavior at either noon or midnight.
The same problem occurs in factories.
A machine may behave differently:
During startup
Under heavy load
While idle
During cleaning
At different ambient temperatures
A useful baseline must reflect the system’s natural cycles.
That might mean comparing today’s 14:00 reading with previous readings around 14:00 rather than with the entire historical dataset.
Rolling Averages Follow Recent Behavior
A rolling average calculates the average over a moving window of recent observations.
Imagine:
10
11
10
12
11
10
30
The overall historical average might not react quickly to the final value.
A rolling average focuses on what happened immediately before it.
SQLite window functions make this particularly useful.
Example:
SELECT
    RecordedAt,
    Value,
    AVG(Value) OVER (
        ORDER BY RecordedAt
        ROWS BETWEEN 9 PRECEDING AND CURRENT ROW
    ) AS RollingAverage
FROM Telemetry
WHERE DeviceID = ?
  AND MetricID = ?
ORDER BY RecordedAt;
This calculates an average using the current row and the previous nine readings.
We now have two values for every measurement:
Actual value
Recent average
A large difference between them may indicate unusual behavior.
Rows Are Not the Same as Time
There is an important catch.
This:
ROWS BETWEEN 9 PRECEDING AND CURRENT ROWmeans ten rows.
It does not mean ten minutes.
If a sensor reports every second, the window covers roughly ten seconds.
If connectivity fails and readings become irregular, those ten rows might cover several minutes.
For regularly sampled telemetry, row-based windows can work well.
For irregular data, you may be better off grouping readings into fixed time buckets first, then running anomaly analysis against those rollups.
This is another reason our previous downsampling architecture becomes useful.
Instead of analyzing unpredictable raw arrival patterns, we can analyze consistent minute summaries.
Comparing a Reading with the Previous Window
There’s another subtle issue in the previous example.
The current reading contributes to its own rolling average.
If a huge spike occurs, it pulls the average upward and partially hides its own abnormality.
For anomaly detection, we may instead want the baseline to contain only the measurements before the current one.
AVG(Value) OVER (
    ORDER BY RecordedAt
    ROWS BETWEEN 10 PRECEDING AND 1 PRECEDING
)
Now the question becomes:
How different is this reading from the ten readings immediately before it?
That is often a cleaner comparison.
Measuring Variability
An average tells us where values tend to sit.
It doesn’t tell us how much they normally move.
Consider two machines.
Machine A:
49.9
50.1
50.0
49.8
50.2
Machine B:
43
56
48
58
45
Both could have an average near 50.
But their normal variability is completely different.
A reading of 55 might be extraordinary for Machine A and completely ordinary for Machine B.
To detect anomalies intelligently, we therefore need a measure of spread.
A common choice is standard deviation.
SQLite doesn’t provide a built-in standard deviation aggregate in its core SQL functions, but we can calculate the required components ourselves.
For a set of values, we need:
Average of x
Average of x²
Variance can then be derived from:
AVG(x²) - AVG(x)²and standard deviation is the square root of variance.
Depending on your SQLite build and math-function support, you can calculate the final square root in SQL or in the application.
Rolling Statistics with Window Functions
We can calculate rolling components like this:
WITH RollingStats AS (
    SELECT
        TelemetryID,
        RecordedAt,
        Value,

        AVG(Value) OVER (
            ORDER BY RecordedAt
            ROWS BETWEEN 30 PRECEDING AND 1 PRECEDING
        ) AS MeanValue,

        AVG(Value * Value) OVER (
            ORDER BY RecordedAt
            ROWS BETWEEN 30 PRECEDING AND 1 PRECEDING
        ) AS MeanSquare,

        COUNT(*) OVER (
            ORDER BY RecordedAt
            ROWS BETWEEN 30 PRECEDING AND 1 PRECEDING
        ) AS SampleCount

    FROM Telemetry
    WHERE DeviceID = ?
      AND MetricID = ?
)
SELECT *
FROM RollingStats
ORDER BY RecordedAt;
From these values:
variance = MeanSquare - MeanValue²We can estimate how far the current measurement sits from normal recent behavior.
This is much more informative than simply comparing everything with one fixed number.
Using a Z-Score
A common statistical measure for this comparison is the z-score.
Conceptually:
z = (current value - mean) / standard deviationA value close to the mean has a z-score near zero.
A value several standard deviations away has a larger positive or negative score.
For example:
Rolling mean = 20
Standard deviation = 2
Current value = 28

z = (28 - 20) / 2
z = 4
That measurement sits four standard deviations above the baseline.
Depending on the data and application, that may be a strong anomaly candidate.
But a z-score should not automatically be treated as proof that something is wrong.
Real sensor data may not follow a neat statistical distribution, and operational processes often have natural spikes.
The score is a signal for investigation, not universal truth.
Avoiding Tiny Baselines
Suppose a device has just started.
We have only three earlier readings:
10.0
10.1
9.9
The calculated variability may be extremely small.
Then a perfectly harmless reading of 10.4 could receive a dramatic anomaly score.
We need a minimum amount of baseline data before trusting the result.
For example:
Minimum samples = 30Until that requirement is met, the application can report:
Baseline not establishedrather than:
ANOMALY!This simple rule can prevent a large number of false alerts after startup.
Zero Variance Needs Special Handling
Imagine a sensor that reports exactly:
5.0
5.0
5.0
5.0
5.0
Its standard deviation is zero.
We cannot divide by zero to calculate a z-score.
The application must explicitly handle this situation.
If the current value is also 5.0, nothing changed.
If the next value suddenly becomes 8.0, the change may be extremely interesting, but it needs special logic rather than a normal z-score calculation.
Production anomaly detection requires these edge cases to be deliberate.
Detecting Sudden Jumps with LAG()
Sometimes we don’t care how a measurement compares with the long-term baseline.
We simply want to know whether it changed abruptly.
SQLite’s LAG() window function is perfect for this.
SELECT
    RecordedAt,
    Value,
    LAG(Value) OVER (
        ORDER BY RecordedAt
    ) AS PreviousValue
FROM Telemetry
WHERE DeviceID = ?
  AND MetricID = ?
ORDER BY RecordedAt;
Now we can calculate:
Value - PreviousValueSuppose pressure readings are:
102
103
103
104
158
The jump from 104 to 158 may be more important than the absolute value 158.
This is useful for:
Pressure spikes
Sudden temperature changes
Voltage changes
Battery drops
Flow interruptions
Unexpected position changes
Anomaly detection is often about change, not just magnitude.
Detecting Drift
Sudden spikes are easy to notice.
Slow drift is harder.
Consider:
20.0
20.1
20.3
20.5
20.8
21.1
21.5
21.9
22.4
Each individual step is small.
But the system is clearly moving away from its earlier state.
One practical approach is to compare a short rolling average with a longer baseline.
For example:
Recent window:     10 minutes
Baseline window:   6 hours
If:
Recent average = 22.1
Long-term average = 20.2
the difference may indicate drift.
This technique is useful because many mechanical problems don’t begin with a dramatic failure.
Bearings wear.
Filters clog.
Temperatures creep upward.
Battery capacity deteriorates.
Small changes accumulate.
Using Rollups for Longer Baselines
Raw telemetry isn’t always the best source for anomaly detection.
Suppose a sensor produces one reading every second.
To calculate a 30-day baseline from raw data, we’d potentially examine millions of rows.
But our previous article already created minute and hourly rollups.
That means we can use:
Raw telemetry       → immediate anomalies
Minute rollups      → short-term patterns
Hourly rollups      → long-term baselines
Daily rollups       → seasonal behavior
This is where the architecture begins to compound in value.
Downsampling isn’t only about saving storage.
It gives later analytics a much smaller dataset to work with.
Building a Baseline Table
For frequently evaluated sensors, recalculating historical baselines repeatedly may be wasteful.
We can materialize them.
Example:
CREATE TABLE SensorBaseline (
    DeviceID INTEGER NOT NULL,
    MetricID INTEGER NOT NULL,
    MeanValue REAL NOT NULL,
    MeanSquare REAL NOT NULL,
    MinimumValue REAL,
    MaximumValue REAL,
    SampleCount INTEGER NOT NULL,
    UpdatedAt INTEGER NOT NULL,

    PRIMARY KEY (DeviceID, MetricID)
);
A background process can periodically refresh these values from recent rollups.
Anomaly checks then become inexpensive:
New reading
    ↓
Read baseline
    ↓
Calculate deviation
    ↓
Classify
This avoids repeatedly scanning historical telemetry for every incoming measurement.
Baselines Can Be Time-Aware
One baseline per device and metric may still be too crude.
Suppose an industrial cooling system normally runs hotter during the afternoon.
Instead of:
Device + Metricour baseline might become:
Device + Metric + HourOfDayNow we can compare:
Tuesday 14:15with the normal behavior around:
14:00rather than with midnight readings.
For weekly cycles, we might include:
DayOfWeekA baseline table could therefore represent:
DeviceID
MetricID
HourOfDay
MeanValue
MeanSquare
SampleCount
This creates a simple seasonal model without introducing a separate analytics platform.
Context Matters More Than Clever Mathematics
Suppose a machine’s vibration rises sharply every morning at 08:00.
A statistical detector may initially classify that as unusual.
Then we discover:
08:00 = production startupThe anomaly isn’t an anomaly at all.
This is why sensor analytics must understand operating context.
Useful context might include:
Machine state
Production mode
Ambient temperature
Shift
Load
Speed
Location
Firmware version
Maintenance state
Instead of asking:
Is 4.8 unusual?
we may eventually ask:
Is 4.8 unusual for this machine while running at this speed under this load?
That produces much more meaningful detection.
Avoid Turning Every Outlier into an Alert
Anomaly detection and alerting are related, but they aren’t the same thing.
Suppose one unusual reading appears:
Normal
Normal
Normal
Anomaly
Normal
Normal
Should someone receive an urgent notification?
Probably not in many systems.
Sensors produce noise.
Wireless packets arrive strangely.
Machines briefly change operating state.
A useful anomaly pipeline may classify a reading as unusual without immediately creating an operational alert.
For example:
Reading
   ↓
Anomaly Detection
   ↓
Anomaly Candidate
   ↓
Persistence / Context Check
   ↓
Alert Decision
This separation becomes very important as the monitoring system grows.
Require Persistence
One practical way to reduce false positives is to require repeated abnormal behavior.
Instead of:
one unusual reading → alertuse:
5 unusual readings
within 2 minutes
→ candidate incident
Or:
rolling average remains abnormal
for 10 minutes
→ candidate incident
This distinguishes transient noise from persistent changes.
The exact rule depends on the sensor.
A safety-critical pressure spike might require immediate action.
A temperature deviation may need to persist before it becomes meaningful.
Store Anomalies Separately
Once an unusual measurement is detected, we don’t necessarily want to rediscover it every time someone opens a dashboard.
Store the detection result.
CREATE TABLE SensorAnomaly (
    AnomalyID INTEGER PRIMARY KEY,
    DeviceID INTEGER NOT NULL,
    MetricID INTEGER NOT NULL,
    RecordedAt INTEGER NOT NULL,
    ObservedValue REAL NOT NULL,
    BaselineValue REAL,
    DeviationScore REAL,
    DetectionMethod TEXT NOT NULL,
    CreatedAt INTEGER NOT NULL
);
Now we have a durable record of what the detection system considered unusual.
This supports:
Dashboards
Diagnostics
Historical analysis
Tuning
Incident investigation
It also lets us compare different detection methods later.
Record Why Something Was Flagged
Don’t store only:
Anomaly = trueStore enough information to explain the decision.
For example:
ObservedValue = 82.4
BaselineValue = 63.1
DeviationScore = 4.7
DetectionMethod = rolling_zscore
Or:
ObservedValue = 18.2
PreviousValue = 10.1
DetectionMethod = sudden_change
Explainability matters.
When an engineer investigates an event two weeks later, they should be able to understand why the system considered it abnormal.
Different Metrics Need Different Detectors
Just as our previous article showed that different metrics need different rollups, they also need different anomaly rules.
Temperature
Useful detectors might include:
Absolute threshold
Rolling deviation
Sustained drift
Vibration
Useful detectors might include:
Sudden spikes
Rolling variability
Long-term baseline change
Battery level
Useful detectors might include:
Unexpected rapid decline
Failure to recharge
Unusual discharge rate
Door state
A statistical average makes little sense.
Instead:
Door open unusually long
Too many state changes
Door opens outside expected hours
The best anomaly detector understands what the metric represents.
Detecting Missing Data
Sometimes the most important anomaly is no measurement at all.
Suppose a sensor normally reports every 60 seconds.
Its latest readings are:
12:01
12:02
12:03
12:04
Current time:
12:17There may be nothing statistically unusual in the recorded values.
The anomaly is the 15-minute silence.
A simple query can find the most recent observation:
SELECT MAX(RecordedAt)
FROM Telemetry
WHERE DeviceID = ?
  AND MetricID = ?;
The application compares that with the expected reporting interval.
This can detect:
Offline devices
Dead batteries
Network failures
Sensor failures
Stalled ingestion pipelines
Absence is data too.
Don’t Confuse Sensor Failure with Real-World Change
Imagine a temperature sensor suddenly reports:
-999Statistically, that’s an enormous anomaly.
Operationally, it may simply be the device’s error value.
Sensor validation should therefore happen before statistical anomaly detection.
The pipeline might be:
Incoming Reading
      ↓
Basic Validation
      ↓
Known Error Codes
      ↓
Range Validation
      ↓
Store Telemetry
      ↓
Anomaly Detection
A broken measurement shouldn’t distort the baseline used to detect real-world problems.
Protect Baselines from Anomalies
This leads to another subtle problem.
Suppose abnormal readings are included when recalculating the baseline.
Over time:
Abnormal behavior
      ↓
Baseline absorbs it
      ↓
Abnormal becomes "normal"
That’s dangerous.
Imagine a motor slowly overheating for several weeks. If the baseline continuously adapts without limits, it may follow the failure upward.
A production design may exclude confirmed anomalies from baseline updates or update baselines slowly enough that meaningful changes remain visible.
Adaptive baselines are useful.
Baselines that blindly chase the latest values are not.
Index for the Analysis You Actually Run
Most anomaly queries repeatedly filter by:
DeviceID
MetricID
RecordedAt
Our existing index remains valuable:
CREATE INDEX idx_telemetry_device_metric_time
ON Telemetry(DeviceID, MetricID, RecordedAt);
For stored anomalies, we might add:
CREATE INDEX idx_anomaly_device_metric_time
ON SensorAnomaly(DeviceID, MetricID, RecordedAt);
But don’t create indexes for every possible analytical question.
Telemetry systems already perform many writes.
Every additional index increases write work and storage.
Add indexes based on real query patterns.
Keep Real-Time Detection Bounded
Running a massive historical query for every new sensor reading is not scalable.
A better architecture separates immediate and historical work.
Incoming Sensor Data
        ↓
SQLite Telemetry
        ↓
Lightweight Detection
        ↓
Anomaly Candidate
Meanwhile:
Historical Rollups
        ↓
Background Baseline Worker
        ↓
SensorBaseline
The real-time path reads a compact baseline rather than rebuilding one from millions of rows.
This keeps ingestion predictable.
A Practical Detection Pipeline
We can now assemble the pieces.
Sensor
   ↓
Validate Reading
   ↓
Store Raw Telemetry
   ↓
Load Relevant Baseline
   ↓
Calculate:
   ├── Threshold violation
   ├── Rolling deviation
   ├── Sudden change
   └── Missing-data state
   ↓
Anomaly Candidate
   ↓
Persistence / Context Rules
   ↓
Store Confirmed Anomaly
Separately:
Raw Telemetry
      ↓
Minute Rollups
      ↓
Hourly Rollups
      ↓
Baseline Worker
      ↓
Updated Baselines
SQLite becomes more than a passive storage engine.
It becomes part of the local analytical pipeline.
Edge Anomaly Detection Has a Major Advantage
Suppose a remote industrial device loses its internet connection.
If anomaly detection exists only in the cloud:
Sensor
  ↓
No network
  ↓
No analysis
But if the edge device stores telemetry and evaluates important conditions locally:
Sensor
  ↓
SQLite
  ↓
Local anomaly detection
  ↓
Local response
analysis can continue even while offline.
When connectivity returns, the device can synchronize:
Raw readings
Rollups
Anomaly records
with the central system.
This is especially useful for remote monitoring, industrial equipment, agricultural systems, vehicles, energy installations, and other environments where connectivity cannot be guaranteed.
Don’t Try to Turn SQLite into a Machine-Learning Platform
SQLite can handle a surprising amount of useful statistical analysis.
But there is an important architectural boundary.
SQLite is excellent for:
Threshold detection
Rolling statistics
Historical baselines
Window calculations
Trend comparisons
Missing-data detection
Local anomaly storage
Lightweight edge analytics
More sophisticated problems may require dedicated tools.
Examples include:
Complex multivariate models
Deep learning
Large fleet-wide model training
High-dimensional pattern recognition
Advanced predictive maintenance models
SQLite can still store the data and model outputs.
It simply doesn’t need to perform every part of the analytical process itself.
Best Practices
For practical sensor anomaly detection with SQLite:
Start with simple rules before adding statistical complexity.
Separate absolute safety thresholds from statistical anomalies.
Compare measurements with relevant baselines, not arbitrary global averages.
Use window functions for rolling calculations and previous-value comparisons.
Remember that row windows are not necessarily time windows.
Exclude the current measurement when it shouldn’t influence its own baseline.
Require enough historical samples before trusting statistical scores.
Handle zero variance explicitly.
Use rollups for long historical baselines.
Model daily or weekly cycles when they materially affect sensor behavior.
Include operating context when possible.
Detect missing readings as well as unusual values.
Validate sensor data before statistical processing.
Avoid allowing anomalies to distort adaptive baselines.
Separate anomaly detection from alerting.
Require persistence when a single abnormal reading isn’t enough.
Store anomaly evidence so decisions remain explainable.
Choose detection methods according to the type of metric.
Keep real-time queries bounded.
Add indexes only for actual analytical access patterns.
Closing Thoughts
The real value of sensor data isn’t simply knowing what a device measured.
It’s knowing when that measurement means something unusual.
SQLite gives us a practical middle ground between basic threshold checks and heavyweight analytics platforms.
With rolling statistics, historical baselines, window functions, time-aware comparisons, and carefully designed anomaly records, we can detect spikes, drift, unexpected changes, missing measurements, and abnormal behavior directly alongside the telemetry itself.
More importantly, the system can explain why something looked unusual.
And that brings us to the next problem.
Detecting an anomaly tells us:
Something unusual may be happening.
A production monitoring system still has to decide:
Should anyone be notified, when should they be notified, and how do we stop the same problem from generating hundreds of alerts?
That’s where stateful alerting begins.
Subscribe Now
Turn Sensor Data Into Actionable Insight
Collecting telemetry is useful, but the real value comes from recognizing when something starts behaving differently.
Subscribe to SQLite Forum for practical tutorials, advanced SQLite techniques, and real-world system design covering time-series data, anomaly detection, edge analytics, monitoring, performance, and production-ready applications.
Subscribe and keep learning how to turn raw SQLite data into useful decisions.