

Phase 3: How SQLite Behaves Under Real Hardware Pressure
Imagine a warehouse where a worker receives a simple instruction: update the delivery address on one package.
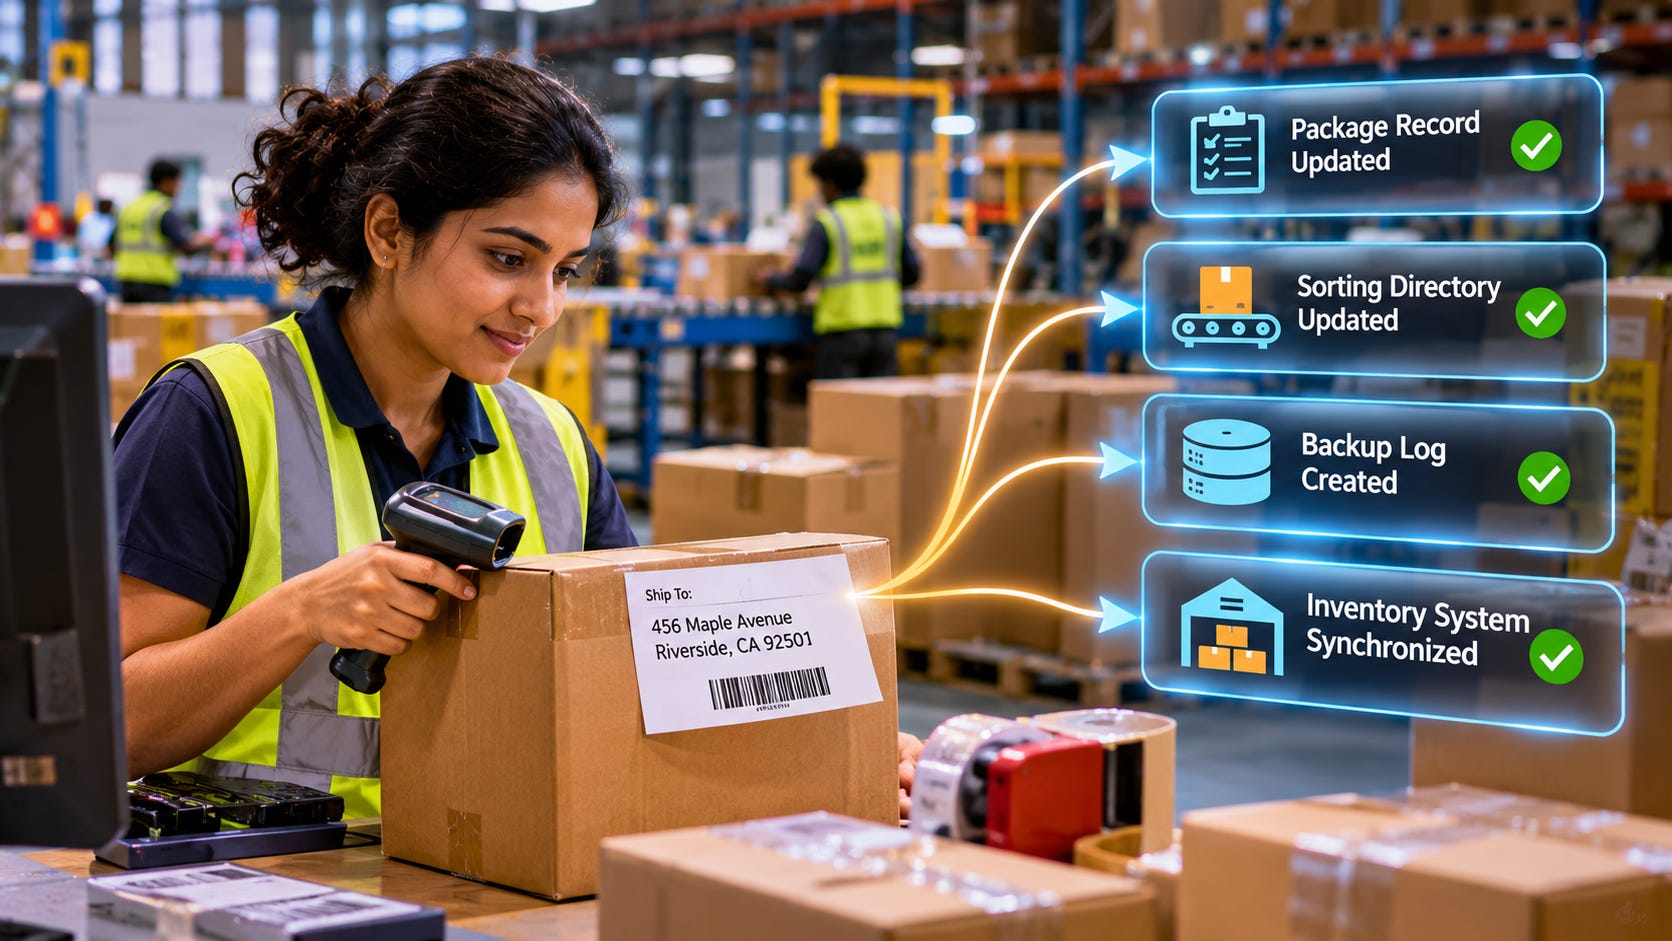
The worker changes the address label. That should be the end of the task.
But the warehouse has several systems that must remain synchronized.
The package record needs updating. The sorting directory must reflect the change. A backup log must record the modification. The warehouse’s central inventory system must eventually receive the updated information.
One small change has triggered several separate operations.
SQLite behaves similarly.
An application might execute a simple statement:
UPDATE Orders
SET Status = 'shipped'
WHERE OrderID = 501;
From the application’s perspective, this changes one value in one row.
But internally, SQLite may need to modify a database page, update one or more indexes, append page images to a Write-Ahead Log (WAL), and eventually copy those pages back into the main database file.
Depending on the storage device, those writes may trigger additional operations inside the hardware itself.
This difference between the logical amount of data changed and the physical work required to store that change is called write amplification.
Write amplification matters because SQLite applications do not operate on abstract rows alone. They operate on database pages, filesystem structures, and physical storage devices.
In our previous article, Implementing the Transactional Outbox Pattern with SQLite, we explored how applications can reliably store business changes and outgoing events together.
That design improves reliability, but every additional event, index, retry, and status update also contributes to the database’s write workload.
As we enter Phase 3 of our SQLite series, we’ll examine what happens beneath the SQL statements.
We’ll explore how SQLite pages, B-trees, indexes, WAL frames, checkpoints, and transaction boundaries influence write amplification, then build practical experiments to measure and reduce unnecessary writes.
1. What Is Write Amplification?
Write amplification describes a situation where storing a small amount of useful application data causes a larger amount of data to be written at lower layers.
For example, imagine an application changes a 10-byte value.
SQLite stores that value inside a database page.
If the database uses a 4 KiB page size, changing a few bytes may cause an entire 4 KiB page image to be written into the WAL.
That is already substantially more data than the application logically changed.
If the same page is later written into the main database during a checkpoint, another page-sized write occurs.
Additional index pages, transaction metadata, and storage-device operations may increase the total further.
A simplified measurement is:
However, the meaning of bytes written must be specified.
We can measure write amplification at several different layers.
Layer                    What we measure
Application              Bytes of logical data changed
SQLite WAL               Bytes appended to the WAL file
SQLite database          Bytes written to the main database file
Operating system         Bytes submitted through filesystem or block I/O
Physical storage         Actual writes performed by the storage device
These measurements are related, but they are not interchangeable.
For example, WAL writes and checkpoint writes are visible at the database-file level, while SSD garbage collection happens inside the storage device.
SQLite does not directly report the number of physical NAND bytes written by an SSD.
For this article, we’ll focus primarily on SQLite-level write amplification, using database pages and WAL activity as observable evidence.
2. SQLite Writes Pages, Not Individual Values
SQLite databases are organized into fixed-size pages.
Common page sizes include:
1,024 bytes
2,048 bytes
4,096 bytes
8,192 bytes
16,384 bytes
SQLite supports additional page sizes up to 65,536 bytes.
The page size is a fundamental unit of database storage.
To inspect the current page size:
PRAGMA page_size;A typical result might be:
4096This means the database uses 4 KiB pages.
Now consider a table:
CREATE TABLE SensorReadings (
    ReadingID INTEGER PRIMARY KEY,
    DeviceID INTEGER NOT NULL,
    Temperature REAL NOT NULL,
    RecordedAt INTEGER NOT NULL
);
Insert a reading:
INSERT INTO SensorReadings (
    DeviceID,
    Temperature,
    RecordedAt
)
VALUES (
    101,
    24.6,
    1790000000000
);
The inserted record may occupy only a small fraction of a page.
But SQLite manages the B-tree pages containing that record.
When a transaction modifies a page, SQLite’s WAL mechanism records page images rather than writing only the changed column bytes.
This is the first important source of write amplification.
A Simple Page-Level Example
Suppose a transaction modifies one 4 KiB page.
The WAL frame contains the page image plus a 24-byte frame header.
Ignoring the WAL file’s initial header, the frame contributes:
Database page:     4,096 bytes
WAL frame header:     24 bytes
--------------------------------
Total:             4,120 bytes
A tiny logical update may therefore generate a 4,120-byte WAL frame.
This does not mean every SQL statement always writes exactly one frame. A statement may modify multiple pages, and multiple modifications to the same page within one transaction can be consolidated.
The amount of writing depends on which pages become dirty and when they are written.
3. How B-Tree Updates Multiply Writes
SQLite stores ordinary rowid tables and indexes using B-tree structures.
A B-tree allows the database to locate and update records efficiently without scanning every row.
But maintaining a B-tree requires modifying its pages.
For example:
CREATE TABLE Orders (
    OrderID INTEGER PRIMARY KEY,
    CustomerID INTEGER NOT NULL,
    Status TEXT NOT NULL,
    TotalAmount INTEGER NOT NULL
);
Insert an order:
INSERT INTO Orders (
    CustomerID,
    Status,
    TotalAmount
)
VALUES (
    1201,
    'pending',
    4999
);
SQLite must update the table’s B-tree.
For a straightforward insertion, this may involve modifying a leaf page.
However, some insertions require additional work.
If the target page lacks sufficient free space, SQLite may reorganize records or split a page.
That can involve updating multiple B-tree pages.
The resulting write workload is larger than the size of the inserted record.
Why Random Updates Can Be Expensive
Consider two workloads.
Workload A:
INSERT INTO Orders (
    CustomerID,
    Status,
    TotalAmount
)
VALUES (
    1202,
    'pending',
    2500
);
Workload B:
UPDATE Orders
SET Status = 'shipped'
WHERE OrderID = 501;
Sequential inserts into a rowid table with increasing rowids often concentrate activity near the right-hand side of the B-tree.
Random updates may touch pages scattered throughout the database.
When a transaction modifies many distinct pages, SQLite may need to write many page images.
This becomes particularly important in batch processing.
Updating 1,000 rows located on a small number of pages can have a different write profile from updating 1,000 rows scattered across hundreds of pages.
The number of rows changed is not always a reliable predictor of the number of pages written.
4. Indexes: Faster Reads, More Write Work
Indexes are among SQLite’s most useful performance features.
They help queries locate matching rows without scanning entire tables.
But indexes also introduce write overhead.
Consider:
CREATE INDEX idx_orders_customer
ON Orders(CustomerID);
Now insert an order.
SQLite must update:
The table B-tree.
The customer index B-tree.
If we add more indexes:
CREATE INDEX idx_orders_status
ON Orders(Status);

CREATE INDEX idx_orders_total
ON Orders(TotalAmount);
A new row may require modifications to four separate B-tree structures.
Those changes can involve several distinct pages.
The resulting WAL may contain more page images than it would without the additional indexes.
Not Every UPDATE Changes Every Index
This distinction is important.
Suppose the application executes:
UPDATE Orders
SET Status = 'shipped'
WHERE OrderID = 501;
The Status index must reflect the new value.
But the CustomerID and TotalAmount indexes do not necessarily require changes because their indexed values remain unchanged.
SQLite’s exact work depends on the statement, schema, constraints, and query plan.
Nevertheless, every index adds maintenance responsibilities for inserts, deletes, and updates that affect its indexed data.
Measuring Index Overhead
We can compare two similar tables.
CREATE TABLE OrdersWithoutIndexes (
    OrderID INTEGER PRIMARY KEY,
    CustomerID INTEGER NOT NULL,
    Status TEXT NOT NULL,
    TotalAmount INTEGER NOT NULL
);

CREATE TABLE OrdersWithIndexes (
    OrderID INTEGER PRIMARY KEY,
    CustomerID INTEGER NOT NULL,
    Status TEXT NOT NULL,
    TotalAmount INTEGER NOT NULL
);
Add indexes to the second table:
CREATE INDEX idx_test_customer
ON OrdersWithIndexes(CustomerID);

CREATE INDEX idx_test_status
ON OrdersWithIndexes(Status);

CREATE INDEX idx_test_total
ON OrdersWithIndexes(TotalAmount);
Populate both tables with equivalent workloads.
Then compare:
Insert throughput
WAL growth
Database page count
Checkpoint activity
Query performance
The indexed table may require more write work, but it may also execute important queries much faster.
The goal is not to remove every index.
It is to retain indexes whose read benefits justify their write and storage costs.
5. Understanding Write Amplification in WAL Mode
SQLite’s Write-Ahead Logging mode changes how database modifications reach persistent storage.
Enable WAL mode:
PRAGMA journal_mode = WAL;In WAL mode, committed changes are first recorded in the WAL file.
The main database file is updated later through checkpointing.
A simplified flow looks like this:
Application UPDATE
        |
        v
Modify Database Pages
        |
        v
Append Page Images to WAL
        |
        v
Commit Transaction
        |
        v
Checkpoint
        |
        v
Copy Pages into Main Database
This architecture provides important benefits.
Readers can continue accessing an existing database snapshot while a writer appends new committed changes to the WAL.
But it also introduces another stage in the write lifecycle.
One Page, Multiple Writes
Suppose a transaction modifies one database page.
The modified page is appended to the WAL.
Later, a checkpoint copies that page into the main database.
At the SQLite-file level, the page’s contents may have been written twice:
Once into the WAL.
Once into the main database.
This is a simplified illustration, not a universal two-times amplification factor.
A checkpoint may copy only the latest version of a page even when multiple versions appear in the WAL.
Conversely, a transaction may modify many pages and indexes.
The exact amplification depends on the workload and checkpoint behavior.
6. Why Transaction Size Matters
Consider an application updating 1,000 sensor records.
One approach commits each update separately.
UPDATE SensorReadings
SET Temperature = 25.1
WHERE ReadingID = 1;
Then another transaction updates the next record, and so on.
This creates 1,000 transaction boundaries.
Now consider grouping the updates.
BEGIN IMMEDIATE;

UPDATE SensorReadings
SET Temperature = 25.1
WHERE ReadingID = 1;

UPDATE SensorReadings
SET Temperature = 25.2
WHERE ReadingID = 2;

UPDATE SensorReadings
SET Temperature = 25.3
WHERE ReadingID = 3;

-- Continue with additional updates.

COMMIT;
If several updates affect the same database page, SQLite can avoid repeatedly writing separate committed versions of that page.
The grouped transaction may therefore produce fewer WAL frames.
It can also reduce transaction and synchronization overhead.
Why Not Use One Enormous Transaction?
Large transactions have tradeoffs.
They may:
Hold the single SQLite writer slot longer.
Increase memory and cache pressure.
Generate substantial WAL growth.
Delay other writers.
Increase recovery and operational complexity.
A practical application often uses moderate batches.
For example:
Batch size: 500 records
Commit
Batch size: 500 records
Commit
Batch size: 500 records
Commit
The best batch size depends on row size, page locality, indexes, concurrency, and storage hardware.
There is no universal optimal value.
Batching should reduce unnecessary writes without creating excessively long write transactions.
7. Checkpoints and Their Effect on Physical Writes
A checkpoint transfers committed WAL content into the main database file.
SQLite supports several checkpoint modes.
PRAGMA wal_checkpoint(PASSIVE);PRAGMA wal_checkpoint(FULL);PRAGMA wal_checkpoint(RESTART);PRAGMA wal_checkpoint(TRUNCATE);These modes differ in how aggressively they attempt to complete checkpointing and whether the WAL can be reset or truncated.
Automatic Checkpointing
SQLite normally enables automatic WAL checkpointing at a threshold of 1,000 pages.
The threshold can be inspected or configured:
PRAGMA wal_autocheckpoint;For example:
PRAGMA wal_autocheckpoint = 2000;This changes the threshold at which automatic checkpointing is attempted.
It does not guarantee that every checkpoint can complete.
Long-running readers may prevent a checkpoint from advancing through all WAL frames.
Checkpoint Frequency and Write Amplification
Checkpoint frequency influences how writes are distributed over time.
Frequent checkpoints may increase repeated main-database page writes when the same pages are modified between checkpoints.
Less frequent checkpoints can sometimes consolidate multiple WAL versions of the same page into fewer database-file writes.
However, delaying checkpoints also allows the WAL to grow.
A large WAL can increase storage requirements and may affect read performance.
The goal is not to eliminate checkpoints.
It is to balance:
WAL size
Checkpoint workload
Reader activity
Write latency
Recovery requirements
Available disk space
Checkpoint tuning should be based on measurements rather than assuming larger or smaller thresholds are always better.
8. Measuring WAL Growth in a Controlled Experiment
Let’s build a reproducible experiment.
We’ll use Python only as a test harness. The database operations themselves remain ordinary SQLite SQL.
The experiment compares repeated small transactions with a single batched transaction.
import os
import sqlite3
import tempfile

def run_experiment(batch_mode):
    with tempfile.TemporaryDirectory() as directory:
        path = os.path.join(directory, "test.db")

        connection = sqlite3.connect(path)

        connection.execute("PRAGMA page_size = 4096")
        connection.execute("PRAGMA journal_mode = WAL")
        connection.execute("PRAGMA wal_autocheckpoint = 0")

        connection.execute("""
            CREATE TABLE Measurements (
                ID INTEGER PRIMARY KEY,
                Value INTEGER NOT NULL
            )
        """)

        connection.executemany(
            "INSERT INTO Measurements (ID, Value) VALUES (?, ?)",
            [(i, 0) for i in range(1, 1001)]
        )

        connection.commit()

        # Start both tests from the same checkpointed baseline.
        connection.execute("PRAGMA wal_checkpoint(TRUNCATE)")

        if batch_mode:
            connection.execute("BEGIN IMMEDIATE")

            for i in range(1, 1001):
                connection.execute(
                    "UPDATE Measurements SET Value = ? WHERE ID = ?",
                    (i, i)
                )

            connection.commit()

        else:
            for i in range(1, 1001):
                connection.execute(
                    "UPDATE Measurements SET Value = ? WHERE ID = ?",
                    (i, i)
                )
                connection.commit()

        wal_path = path + "-wal"

        wal_bytes = (
            os.path.getsize(wal_path)
            if os.path.exists(wal_path)
            else 0
        )

        connection.close()

        return wal_bytes

individual = run_experiment(False)
batched = run_experiment(True)

print("Individual transactions:", individual, "bytes")
print("Batched transaction:", batched, "bytes")

if batched:
    print("WAL size ratio:", round(individual / batched, 2))
What This Experiment Demonstrates
Both tests update the same 1,000 records.
The difference is transaction grouping.
With individual transactions, SQLite repeatedly commits changes, potentially writing multiple versions of the same pages.
With one batched transaction, multiple row updates affecting the same page can be consolidated before commit.
We should generally expect the batched workload to generate less WAL data in this experiment.
But the exact result depends on SQLite version, page layout, and other runtime details.
The script measures WAL file growth, not total physical SSD writes.
That distinction matters when interpreting the results.
9. Measuring the Cost of Additional Indexes
Let’s extend the experiment.
Create a table with several indexed columns:
CREATE TABLE Events (
    EventID INTEGER PRIMARY KEY,
    DeviceID INTEGER NOT NULL,
    EventType TEXT NOT NULL,
    Severity INTEGER NOT NULL,
    RecordedAt INTEGER NOT NULL
);
Add indexes:
CREATE INDEX idx_events_device
ON Events(DeviceID);

CREATE INDEX idx_events_type
ON Events(EventType);

CREATE INDEX idx_events_severity
ON Events(Severity);

CREATE INDEX idx_events_recorded
ON Events(RecordedAt);
Now insert a large batch of events.
BEGIN IMMEDIATE;

INSERT INTO Events (
    DeviceID,
    EventType,
    Severity,
    RecordedAt
)
VALUES
    (101, 'temperature', 2, 1790000000000),
    (102, 'pressure', 3, 1790000001000),
    (103, 'temperature', 1, 1790000002000);

COMMIT;
For a meaningful benchmark, generate thousands of equivalent records and compare the results against a table without the secondary indexes.
Measure WAL bytes and elapsed time separately.
Why separately?
Because write amplification and execution time are related but distinct.
An indexed table may generate more writes yet still perform acceptably because its working set remains cached.
Conversely, an index may cause significant random I/O when the dataset exceeds available memory.
The correct optimization depends on the actual workload.
10. Page Size and Write Amplification
Page size influences the granularity of SQLite’s database writes.
A larger page can store more records.
That may reduce the number of B-tree pages required for some workloads.
But a larger page also means more bytes per WAL frame.
Consider two configurations:
Configuration	Page size
Database A	4 KiB
Database B	16 KiB
If a transaction modifies one page, the corresponding WAL frame contains approximately:
Database A: 4,096 + 24 = 4,120 bytes

Database B: 16,384 + 24 = 16,408 bytes
This suggests that smaller pages may be advantageous for workloads involving sparse, localized updates.
However, larger pages may improve efficiency when records are large or when operations modify substantial portions of each page.
They may also change B-tree height, overflow behavior, and cache efficiency.
Changing Page Size
For a new database, configure page size before creating tables:
PRAGMA page_size = 8192;For an existing database, changing page size generally requires rebuilding the database with VACUUM, and SQLite does not support changing page size through VACUUM while the database is operating in WAL mode.
Page-size changes should therefore be planned carefully.
Do not change page size simply because a benchmark shows a larger or smaller WAL file in one test.
Evaluate query performance, transaction latency, cache behavior, and total storage activity together.
11. Understanding Write Amplification on SSDs
SQLite’s write behavior interacts with the storage device beneath the filesystem.
Modern SSDs typically use flash memory.
Flash memory has characteristics that differ from traditional magnetic disks.
Data is written in pages but erased in larger blocks.
Updating existing logical data may require the SSD controller to write new physical locations and later reclaim obsolete storage.
This process can create additional internal writes.
SQLite-Level vs SSD-Level Amplification
Consider:
Application changes:
        100 bytes
            |
            v
SQLite WAL writes:
      Several KiB
            |
            v
SQLite checkpoint writes:
      Additional KiB
            |
            v
SSD controller:
      Internal data movement
The physical NAND write volume may exceed the bytes submitted by SQLite and the operating system.
But SQLite’s WAL size alone cannot tell us the SSD’s internal amplification factor.
That requires storage-specific telemetry or hardware measurement.
Why This Matters for Embedded Devices
Write amplification is especially relevant when SQLite runs on:
Industrial controllers
IoT gateways
Mobile devices
Edge computers
Flash-based embedded systems
These environments may have limited write endurance, storage bandwidth, or power budgets.
Reducing unnecessary database writes can improve performance and reduce storage wear.
However, durability settings should not be weakened casually.
For example, changing PRAGMA synchronous affects synchronization and crash-durability behavior. It is not simply a free write-amplification optimization.
Any such change must be evaluated against the application’s failure and data-loss requirements.
12. The Hidden Cost of Frequent Status Updates
Consider the transactional outbox from our previous article.
Each event may pass through several states:
pending
   |
   v
publishing
   |
   v
published
Each transition updates the outbox table.
If status and scheduling fields are indexed, those transitions may also modify index pages.
Now imagine processing 100,000 events.
The application performs:
100,000 outbox inserts
100,000 claim updates
100,000 completion updates
Additional retry updates
Eventually, retention deletes
One logical business event can therefore generate several database write operations.
This does not mean the outbox is inefficient or should be avoided.
It means reliability mechanisms have measurable storage costs.
Reducing Unnecessary State Changes
Possible improvements include:
Avoiding redundant updates when a record is already in the desired state.
Updating heartbeat timestamps only as frequently as required by the lease design.
Keeping frequently modified records compact.
Indexing only fields required by actual queries.
Processing appropriate groups of records in transactions.
Removing completed records according to a controlled retention policy.
These optimizations must preserve correctness.
For example, removing lease updates without redesigning worker recovery could introduce duplicate execution or permanently abandoned work.
Write reduction is useful only when it does not undermine the reliability guarantees the system depends on.
13. A Practical Write-Optimization Strategy
When investigating excessive SQLite writes, start with the workload rather than immediately changing database settings.
Step 1: Identify the Write-Heavy Operations
Determine which SQL statements execute most frequently.
Typical candidates include:
INSERT INTO Telemetry (...);UPDATE JobQueue SET Status = ...;UPDATE OutboxEvents SET AttemptCount = ...;DELETE FROM Events WHERE RecordedAt < ...;For each operation, identify how many rows and indexes it may modify.
Step 2: Inspect the Schema
List the indexes:
SELECT
    name,
    tbl_name,
    sql
FROM sqlite_schema
WHERE type = 'index';
Review whether each index serves a meaningful query or constraint.
Do not remove indexes required for uniqueness, referential integrity, or critical lookup performance.
Step 3: Measure WAL Activity
Inspect the WAL checkpoint state:
PRAGMA wal_checkpoint(PASSIVE);The result reports checkpoint status information, including WAL frame counts.
This can help reveal checkpoint backlog.
However, a checkpoint command changes checkpoint state, so it is not a completely passive measurement of the system’s behavior.
For repeatable benchmarks, also record WAL file sizes and transaction counts under controlled conditions.
Step 4: Test Batching
Compare individual transactions with moderate batches.
Measure:
WAL bytes generated
Transactions per second
Average latency
High-percentile latency
Concurrent writer delays
Checkpoint duration
Step 5: Test Index Changes
Remove or redesign only indexes whose costs outweigh their benefits.
Re-run both write and read benchmarks.
Step 6: Test Checkpoint Behavior
Evaluate whether checkpoint scheduling affects latency or repeated database-file writes.
Do not optimize solely for the smallest WAL file.
Step 7: Test Under Realistic Hardware Conditions
A benchmark on a fast desktop SSD may not represent an embedded device using inexpensive flash storage.
Test with realistic data sizes, concurrency, storage capacity, and durability requirements.
14. Common Write Amplification Mistakes
Several assumptions can lead developers toward the wrong optimizations.
Assuming one row update means one small disk write. SQLite operates on database pages, not isolated column bytes.
Assuming every index is free after creation. Indexes require ongoing maintenance.
Assuming WAL always reduces total bytes written. WAL improves concurrency and changes write patterns, but checkpoints can introduce additional database-file writes.
Assuming larger transactions are always better. Batching can reduce repeated page writes, but excessively long transactions increase contention.
Assuming smaller pages always reduce amplification. Smaller pages reduce individual frame size but may increase the number of pages needed.
Assuming WAL file size equals SSD wear. Hardware-level amplification includes activity not visible from SQLite.
Disabling durability safeguards to improve benchmarks. Lower synchronization costs may come with unacceptable data-loss risks.
Optimizing writes without measuring reads. Removing indexes can reduce writes while making important queries dramatically slower.
Ignoring maintenance operations. Checkpoints, deletes, and database rebuilding also contribute to storage activity.
15. Best Practices for Write-Heavy SQLite Applications
For applications handling frequent inserts, updates, queues, and event streams, use these principles:
Measure logical changes and database-file writes separately.
Understand the database’s page size and B-tree layout.
Keep secondary indexes intentional.
Batch related writes when practical.
Avoid unnecessary updates to frequently modified rows.
Monitor WAL growth and checkpoint progress.
Prevent long-running readers from indefinitely delaying checkpoints.
Choose page size based on measured workload behavior.
Avoid excessively large transactions that block other writers.
Account for write overhead introduced by durable queues and event-processing systems.
Test on hardware representative of the production environment.
Preserve required durability guarantees while optimizing storage activity.
Closing Thoughts
A SQL statement describes a logical operation.
But SQLite must translate that operation into changes across database pages, B-tree structures, indexes, WAL frames, and eventually persistent storage.
A small update may produce several page-sized writes.
A heavily indexed table may require more maintenance than expected.
A series of individual transactions may repeatedly write the same pages.
And a checkpoint may add another stage of database-file writing.
These behaviors are not necessarily signs of inefficiency.
They are consequences of maintaining transactional consistency, query performance, and crash recovery.
The challenge is understanding where those costs arise and deciding which are necessary.
The goal is not to eliminate writes. It is to ensure that every additional write contributes meaningful value to the application’s performance, correctness, or reliability.
As we continue Phase 3, we’ll move closer to the physical storage layer.
Write amplification becomes particularly important when SQLite runs on flash-based hardware with limited endurance and constrained I/O performance.
That brings us to the next topic.
Coming Next: SQLite on Flash Storage
Understanding SSD and eMMC behavior, storage endurance, filesystem interactions, and practical SQLite tuning for flash-based devices.
Subscribe Now
Understand What Really Happens Inside SQLite
A single SQL update can trigger far more disk activity than expected. Understanding how SQLite handles pages, indexes, WAL files, and checkpoints is essential for building applications that perform efficiently under real hardware pressure.
Subscribe to SQLite Forum for practical tutorials on SQLite internals, write amplification, storage optimization, database performance, and production-ready architectures.
Subscribe Now and take your SQLite expertise beyond SQL queries, into the storage engine itself.